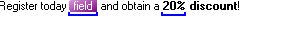
Recognized tokens are source document content that has been recognized as:
Content not requiring translation.
Content which can be automatically localized by applying a translation memory. For example, some dates can automatically be converted to the correct format by applying a translation memory.
Markup tags, placeholder tags, numbers, variables, dates, acronyms and alphanumeric strings are all examples of recognized tokens.
They are identified in the Editor window by a blue square-bracket underline.
The underline is only displayed when you have a translation memory open and the cursor is in the segment where the recognized token is located.
How to Perform a Lookup and Apply Translations