

| Creating a File-based Translation Memory |
In this chapter you will learn how to programmatically create a file-based translation memory, i.e. an *.sdltm file.
 Add a New Class
Add a new class to your project called TmCreator. Then, add a public function called CreateFileBasedTM() to the new class. This function takes tmPath as string parameter, which specifies the path and file name of the TM to be created. This function can be called as shown below:
C#
TMCreator objCreate = new TMCreator();
objCreate.CreateFileBasedTM(_translationMemoryFilePath);
Within the function, start by creating a TM object as follows:
C#
public void CreateFileBasedTM(string tmPath)
{
    FileBasedTranslationMemory tm = new FileBasedTranslationMemory(
        tmPath,
        "This is a sample TM",
        CultureInfo.GetCultureInfo("en-US"),
        CultureInfo.GetCultureInfo("de-DE"),
        this.GetFuzzyIndexes(),
        this.GetRecognizers(),
        TokenizerFlags.AllFlags,
        WordCountFlags.AllFlags
        );

    tm.LanguageResourceBundles.Clear();

    tm.Save();
}
- The full file name and path.
- The TM description string (which can also be empty.)
- The source and target language. The language is specified through the CultureInfo, which is created by the GetCultureInfo method. This method takes the language locale as string parameter. To create a TM with the language direction English (US) -> German, provide en-US and de-DE as parameters. Note that providing an invalid locale string (e.g. en-DE) will throw an exception.
-
Moreover, you need to specify the fuzzy indexes that should be created for the TM. Here you specify
whether a fuzzy index should be created and maintained for the source and/or target segments.
The fuzzy index is required for performing concordance searches, which allow translators to select
one or several words in a source or target segment and search for all occurrences in the TM. By creating
a fuzzy index for both the source and the target, you enable the TM for concordance searches in
both languages.
The concordance search can be word- or character-based. Character-based potentially yields more
results as this kind of search is more tolerant. For example, with a character-based concordance
search the user might enter revolution and get a result such as
revolving, as this result matches some of the search characters.
In this case, a word-based concordance search would not present revolving as a result,
as this word differs to much from the search expression. However, you need to consider that
character-based concordance searches
are significantly slower than word-based searches, especially in large TMs. Character-based indexing
is therefore only recommended for small TMs, which contain e.g. a few hundred or a few thousand segments.
Also note that users will generally want to do concordance searches both in the source and target language.
For our simple example we assume that we enable word- and character-based indexing
for both the source and the target segments. As parameter we provide a separate helper function,
which contains all available
FuzzyIndexes
enumerator values, i.e:
C#
private FuzzyIndexes GetFuzzyIndexes()
{
    return FuzzyIndexes.SourceCharacterBased |
        FuzzyIndexes.SourceWordBased |
        FuzzyIndexes.TargetCharacterBased |
        FuzzyIndexes.TargetWordBased;
}
-
The recognition settings are used to identify elements that do not change during translation such
as numbers, dates, acronyms, etc.
When the recognition settings are enabled these items are identified as placeables.
Placeables can be transferred directly from the current source segment to the new target segment
without having to type them manually. When you create a TM in SDL Trados Studio 2017, all
recognition settings are enabled by default. In our example we use a GetRecognizers
helper function that returns all possible values of
BuiltinRecognizers,
thereby
enabling our sample TM for all recognition types.
C#
private BuiltinRecognizers GetRecognizers()
{
    return BuiltinRecognizers.RecognizeAcronyms |
        BuiltinRecognizers.RecognizeDates |
        BuiltinRecognizers.RecognizeNumbers |
        BuiltinRecognizers.RecognizeTimes |
        BuiltinRecognizers.RecognizeVariables |
        BuiltinRecognizers.RecognizeMeasurements;
}
The screenshot below illustrates the TM recognition settings in SDL Trados Studio 2017:
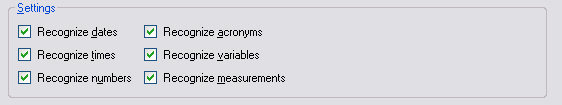
Putting it All TogetherThe complete class should now look as shown below:
C#
namespace Sdl.SDK.LanguagePlatform.Samples.TmAutomation
{
    using System.Globalization;
    using Sdl.LanguagePlatform.Core.Tokenization;
    using Sdl.LanguagePlatform.TranslationMemory;
    using Sdl.LanguagePlatform.TranslationMemoryApi;

    public class TMCreator
    {
        #region "create TM"
        public void CreateFileBasedTM(string tmPath)
        {
            FileBasedTranslationMemory tm = new FileBasedTranslationMemory(
                tmPath,
                "This is a sample TM",
                CultureInfo.GetCultureInfo("en-US"),
                CultureInfo.GetCultureInfo("de-DE"),
                this.GetFuzzyIndexes(),
                this.GetRecognizers(),
                TokenizerFlags.AllFlags,
                WordCountFlags.AllFlags
                );

            tm.LanguageResourceBundles.Clear();

            tm.Save();
        }
        #endregion

        #region "get fuzzy indexes"
        private FuzzyIndexes GetFuzzyIndexes()
        {
            return FuzzyIndexes.SourceCharacterBased |
                FuzzyIndexes.SourceWordBased |
                FuzzyIndexes.TargetCharacterBased |
                FuzzyIndexes.TargetWordBased;
        }
        #endregion

        #region "get recognizers"
        private BuiltinRecognizers GetRecognizers()
        {
            return BuiltinRecognizers.RecognizeAcronyms |
                BuiltinRecognizers.RecognizeDates |
                BuiltinRecognizers.RecognizeNumbers |
                BuiltinRecognizers.RecognizeTimes |
                BuiltinRecognizers.RecognizeVariables |
                BuiltinRecognizers.RecognizeMeasurements;
        }
        #endregion
    }
}
See AlsoOther Resources
CommunityComments